Your AI Agents Are Only as Good as Your Data
The bottleneck isn't your AI model. It's what's behind it.
Better agents won't fix fragmented documents or inconsistent data. The real work is building the knowledge foundation every agent depends on.
There is a pattern emerging quietly across enterprise AI deployments: agents that perform well in demos begin to contradict each other in production. A revenue agent draws one conclusion. A customer support agent draws another. Both are pulling from the same business — but not from the same version of its knowledge. The model isn’t the problem. The data behind it is.
Context Engineering Was Never Enough
Most enterprise AI has been built around what engineers call context engineering: connecting systems, generating embeddings, building retrieval pipelines, and assembling just enough knowledge for a single agent to function. For a standalone assistant or copilot, this works reasonably well. The problems surface when an organisation moves from one AI application to many.
At that point, different teams begin processing the same documents independently. Separate embeddings get built from the same source files. Indexes diverge. Business definitions — for the same product, the same customer, the same process — become inconsistent across agents. No one planned for this. It’s simply what happens when knowledge is treated as application-specific context rather than shared enterprise infrastructure.
The result is three compounding failures: inconsistency (different agents develop different understandings of the business), propagation lag (when a document changes, not every agent’s context updates), and duplication (the same knowledge pipeline gets rebuilt, at cost, for every new application). These are not fundamentally AI problems. They are knowledge management problems — the same class of problem that enterprise data platforms solved for structured data a decade ago.
The Architecture That Changes the Calculus
What the research now points toward is a layered enterprise knowledge platform — not a smarter retrieval trick, but a managed data foundation that sits beneath every agent. The principle is straightforward: ingest enterprise knowledge once, normalise it, connect it across systems using shared business identifiers and relationships, then serve it in whatever representation each agent needs.
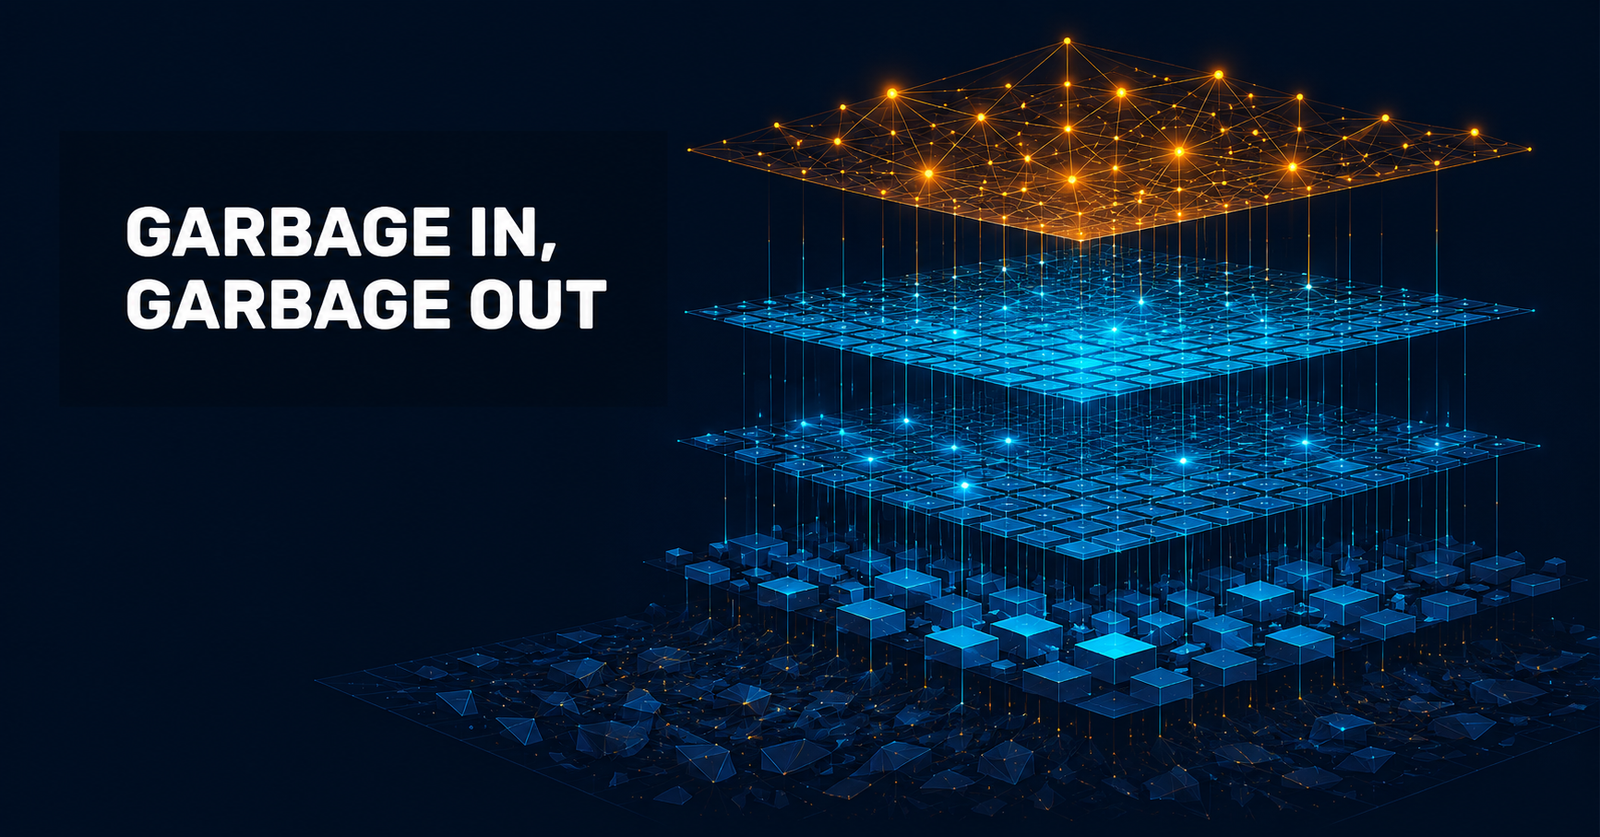
In practice this means separating four distinct responsibilities. Raw sources — documents, tickets, emails, code repositories, API responses — are preserved in original form so they can always be reprocessed. A refinement layer normalises those sources into consistent, governed knowledge objects with metadata, lineage, and permissions intact. An integration layer connects objects across domains using business logic: which requirement was implemented by which engineering ticket, which release note corresponds to which product capability. A serving layer then publishes both shared representations (search indexes, embeddings, graph models) and agent-specific context assembled dynamically from that common foundation.
The distinction matters. A product agent, a revenue agent, and a customer support agent may all consume the same underlying enterprise knowledge model while receiving context tailored to their specific responsibilities — without any team rebuilding the pipeline from scratch.
The next bottleneck is no longer the model or the agent framework. It is the enterprise data foundation behind them.
What This Means for Businesses Running Autonomous Agents
The principle applies with particular force to any organisation deploying autonomous agents at scale. As agent deployments multiply across a business, the absence of a shared knowledge foundation doesn’t just slow things down — it actively undermines the reliability of every agent in the fleet. An agent that books, qualifies, follows up, or handles intake is only as trustworthy as the business knowledge it draws on. If that knowledge is fragmented across siloed pipelines, the agent will produce fragmented outputs.
Governance becomes equally important. A managed knowledge platform preserves lineage — the ability to trace any agent response back to its original source, with version history and permission controls intact. That traceability is not a nice-to-have. It is the mechanism through which human oversight remains meaningful as agent autonomy increases. Governed autonomy depends on knowing what the agent knew, and when it knew it.
The competitive advantage in enterprise AI is shifting. It no longer belongs to the organisation that deploys the most agents, or that runs the largest model. It belongs to the organisation that builds the cleanest, most consistent, most governed knowledge foundation underneath those agents. Garbage in, garbage out remains the most durable principle in data engineering — and it applies to autonomous AI with compounding consequences.
Further Reading: venturebeat.com
Ready to Put Agentic AI to Work?
See how autonomous AI agents can handle booking, intake, and follow-up for your business.


